Free-Public-Tools
Free tools for AI assistants and coding agents, a new one every week. Each started in my own work with AI and is tested before release.
- Published
- Role
- Author: each tool, its tests and its pages, built with AI assistance
- Summary
- Five tools published, each with its own page, notes and every version, and one published test with all its marks.
Context
Free-Public-Tools are free tools for AI assistants and coding agents, released one a week. Each one started in my own work with AI and is tested before release: instructions, commands, subagents and small checkers that I use myself. Use, copy, change and share them however you like, with no need to credit anyone (MIT-0).
What is in it
Each tool has its own page. Copy it in one tap and paste it where it goes: in a chat, in a chat app’s custom instructions, a CLAUDE.md or AGENTS.md file, or your coding agent. A tool made of several files copies as an install prompt that fetches the folder for you. The first five:
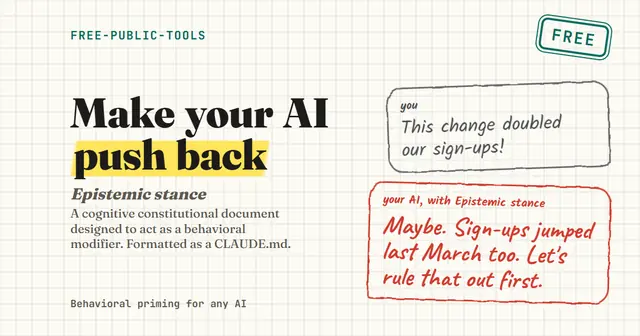
Epistemic stance: make your AI push back with evidence instead of agreeing, and say how sure it is about the claims that matter.
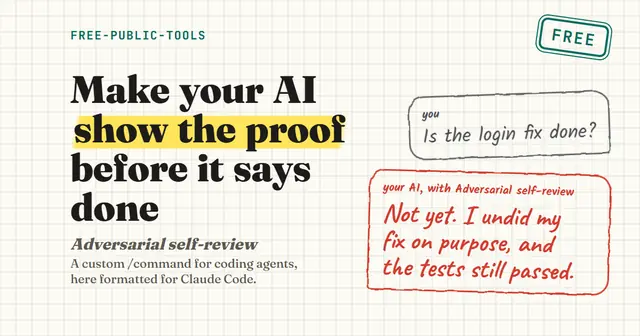
Adversarial self-review: a command that has your coding agent check its own change before calling it done, with pasted evidence for each check.
Claim auditor: a subagent that checks every claim in a README, changelog or benchmark write up before you post it, and grades each one.
Decision challenge: a command that pressure tests one decision before it becomes hard to reverse.
Agent assets lint: a small Node tool that checks instruction files, skills and agent files against rules you write in one JSON file.
Evidence
Everything is public: the tools site, and the repository, where every tool’s folder holds the tool, a README with what it does and where it goes, and all its versions.
The first published test put Decision challenge against two plain prompts on 18 decisions from six of my own projects, across seven AI models: 378 runs on 14 October 2026. Answer keys were written before the runs, and replies were marked without the markers knowing which version or model wrote them. No message asked for an edit, yet 21 of 126 runs with the short prompt and 43 with the plain request edited or deleted project files; with the command, none did. In real use it got 70% of decisions right, against 60% and 51%. With six projects and one run per model and question, a gap of a few points is noise, and I wrote the questions myself. Every question and every mark is on the test page.
Current state
Five tools are out and the series adds one a week. Found a problem, or a tool that does not behave the way its README says? Open an issue.